融合多种使用词信息方法的命名实体识别研究
2021-10-19 13:16:22郭鹏刘俊南
现代信息科技
2021年6期
郭鹏 刘俊南
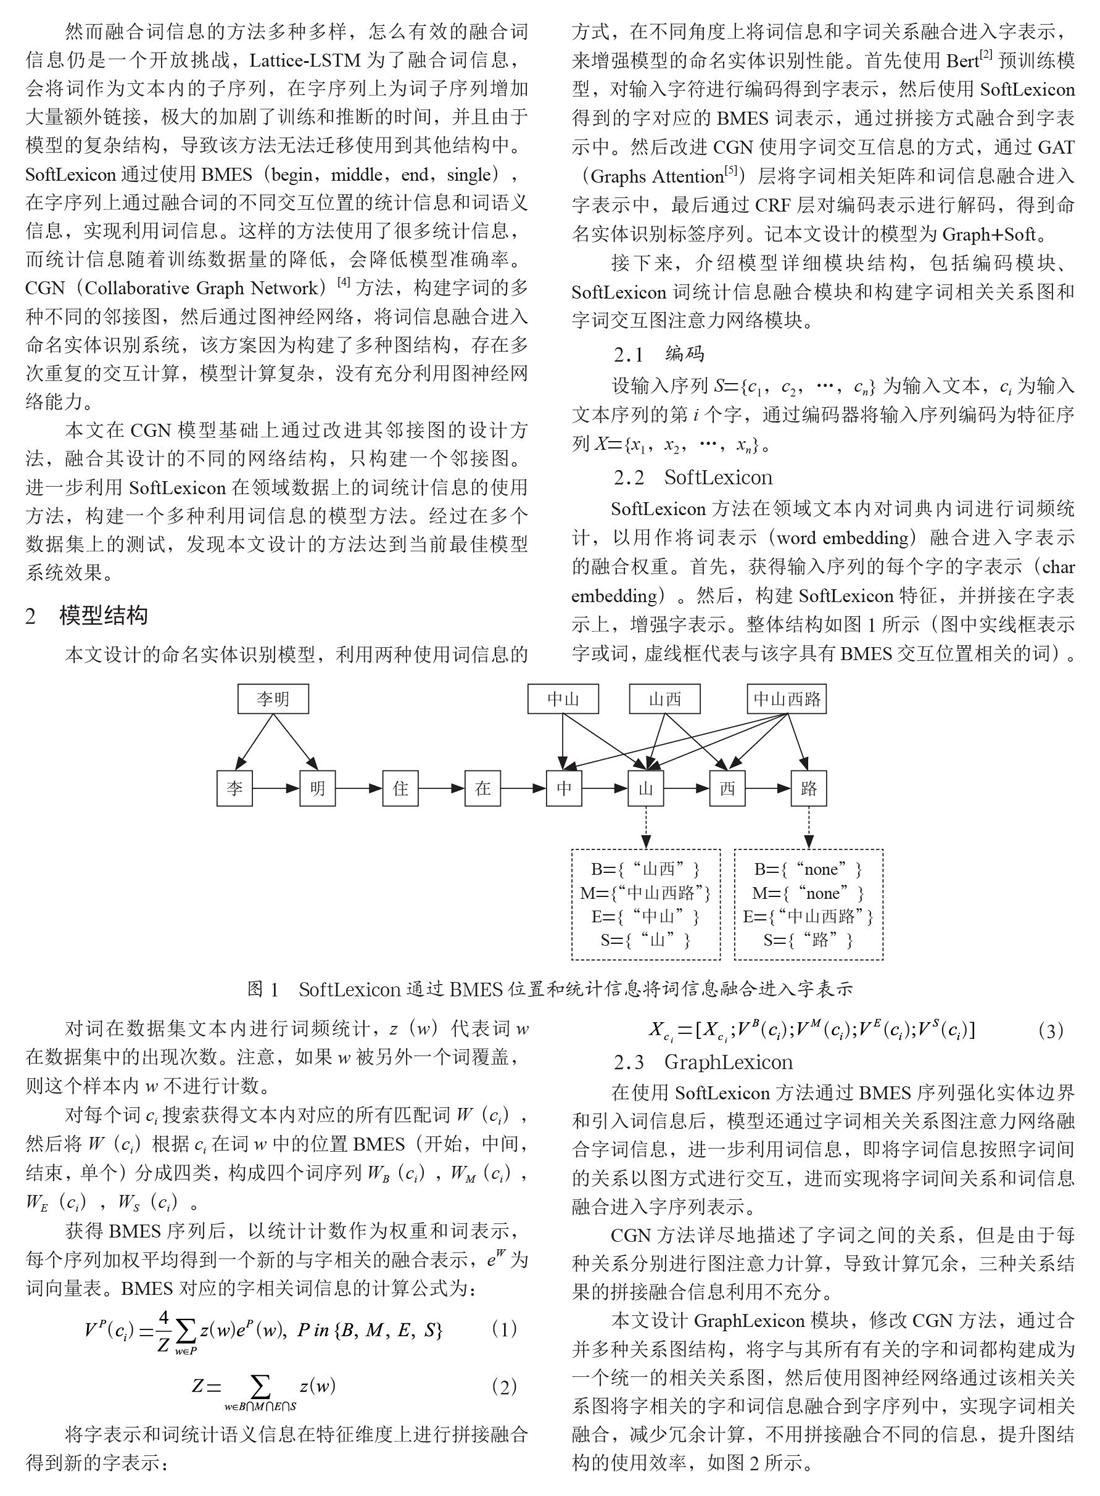
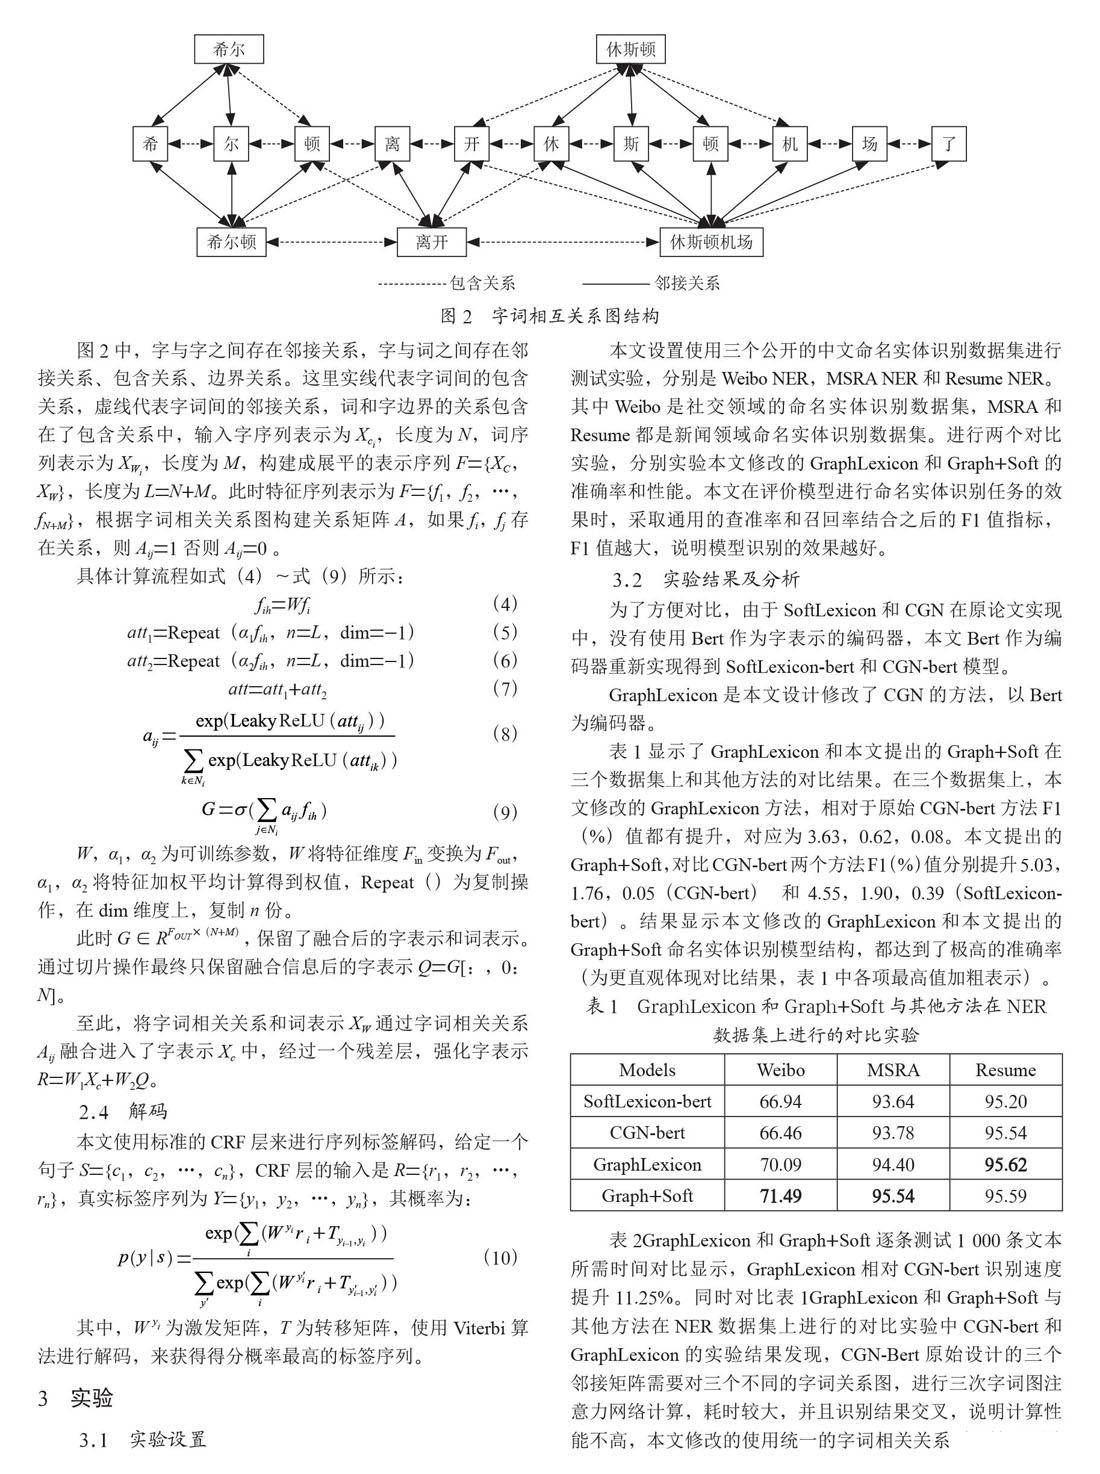
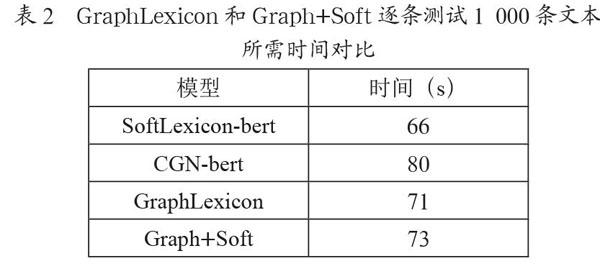
摘 要:文章对融合词信息增强中文命名实体识别问题进行了研究,提出一种用于中文命名实体识别的融合词信息神经网络模型系统。首先使用预训练语言模型Bert对字进行编码得到字标识,然后使用SoftLexicon基于统计的方法将词统计语义信息融合进入字表示中,之后使用设计的GraphLexicon根据文本内字、词之间的交互关系图结构,将字词信息表示相互融合,达到较高的命名实体识别准确率。
关键字:中文命名实体识别;图神经网络;融合;词信息;字词交互;图结构
中图分类号:TP183 文献标识码:A 文章编号:2096-4706(2021)06-0025-04
Research on Named Entity Recognition Based on Multiple Words Used
Information Methods
GUO Peng,LIU Junnan
(Innovem Technology (Tianjin)Co.,Ltd.,Tianjin 300384,China)
Abstract:In this paper,the problem of enhancing Chinese named entity recognition by fusing word information is studied,and a neural network model system based on fusing word information for Chinese named entity recognition is proposed. First,the pre training language model Bert is used to encode the character to get the character identification,and then the statistic based approach SoftLexicon is used to fuse the word statistical semantic information into the character representation. Then,according to the structure of the interaction graph between characters and words in the text,the character and word information representation are fused to achieve a high accuracy of named entity recognition.
Keywords:Chinese named entity recognition;graph neural network;fuse;word information;character and word interaction;graph structure
0 引 言
中文命名实体(Named Entity Recognize,NER)[1]识别是指标记识别出输入文本中特定的实体,并确定该识别类型,例如人名,地名,机构名称,手术名称,患病部位等。命名实体识别经常作为其他自然语言处理系统的预处理步骤,例如关系抽取,事件抽取,问答系统等。作为自然语言文本结构化系统的重要部分,为了构建结构化系统,提升中文命名实体识别的准确率是非常重要的。
早期的命名实体识别大多是基于规则的方法,但是由于语言结构本身具有不确定性,制定出统一完整的规则难度较大。现阶段针对命名实体识别问题最有效的方法是机器学习的方法。传统的机器学习的命名实体识别方法大多采用有监督的机器学习模型,如SVM、HMM、CRF等。最近几年深度学习在自然语言处理上得到广泛的应用,如循环神经网络BiLSTM-CRF,卷积循环神经网络BiLSTM-CNN-CRF,图神经网络模型GraphNN以及许多其他方案模型,如将命名实体识别作为问答解决的变体模型。……
登录APP查看全文
猜你喜欢
今日农业(2021年19期)2022-01-12 06:16:36
中老年保健(2021年11期)2021-08-22 03:15:44
中学生数理化(高中版.高考数学)(2021年1期)2021-03-19 08:28:38
现代出版(2020年3期)2020-06-20 07:10:34
中华手工(2017年2期)2017-06-06 23:00:31
Coco薇(2016年2期)2016-03-22 02:42:52
Coco薇(2015年1期)2015-08-13 02:47:34
小雪花·成长指南(2015年4期)2015-05-19 14:47:56
中外会展(2014年4期)2014-11-27 07:46:46
祝您健康(1987年3期)1987-12-30 09:52:32